
Qwen models are common favorites in the local LLM community, especially for agentic AI systems. So the release of Qwen3.8 27B last week was bound to make some noise, especially with some of the new features on offer. Offering flexible thinking control, native support for vision-language understanding, and “long-horizon agentic tasks,” Qwen3.8 27B looks on paper like a pretty exciting way to access advanced AI reasoning on home PC hardware.
As it turns out, that’s a massive understatement. In a year that’s been packed with exciting developments for local LLMs, Qwen3.8 27B’s uncanny intelligence might be the standout innovation. It brings reasoning capabilities that nip at the heels of frontier models, yet it’s compact and efficient enough to run on consumer-grade home PC hardware. To be clear, Qwen3.8 27B isn’t a one-to-one replacement for frontier AI models operating out of data centers. More than any other model I’ve used, Qwen3.8 27B takes its time to reason through requests, and its token usage is accordingly high.
But this model easily breaks through the biggest obstacle that was holding back my usage of local AI models. Offering an incredible level of intelligence in a footprint that fits comfortably in the 32GB of VRAM offered by today’s top-tier consumer graphics card, Qwen3.8 27B upends the conventional wisdom about what you can accomplish with local AI.
System and usage notes
For many people, agentic AI is all about smaller tasks repeated in the background. They prefer efficient, fast-running models that easily fit into consumer hardware like a mini PC. Such a system is great for processing big folders of document scans, keeping an eye on the movement of certain stocks, creating a smart home that’s actually smart, and much more.
For my work, I’m much more interested in using AI like it’s an overqualified personal assistant. I want to feed it lots of data on lots of moving parts, things like key metrics and schedules and strategy and goals and priorities, and have it help me keep track of it all. From a certain perspective, I’m the ideal user for cloud-based AI subscriptions like Claude, except for one key thing: I need my data to stay private.

So instead of paying yet another monthly bill, I’ve been exploring ways that I can run AI on the PC hardware I already own. Because I work for one of the world’s longest-running PC hardware companies, I’m more than a little spoiled with high-end hardware. Here’s the system that I’m running:
- CPU: AMD Ryzen 9 7950X3D
- Motherboard: ROG Crosshair X870E Apex
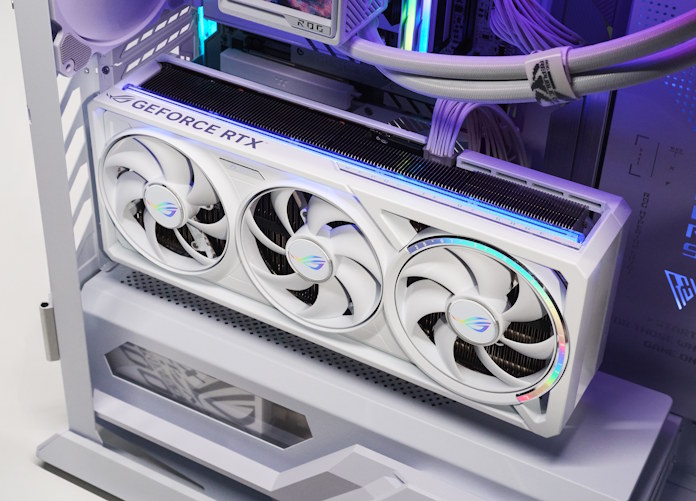
- GPU: ROG Astral LC GeForce RTX 5090
- Memory: 96GB DDR5
- Storage: 2TB PCIe 4.0 SSD
At Q4 quantization, Qwen3.8 27B needs about 16GB of VRAM just for weights, so 16GB graphics cards are essentially off the table once you factor in context and overhead. Typically, I need a large context window, so I bumped it up to 70144 tokens, which leaves about 6GB free for other system processes. A quick look at the performance tab in Windows Task Manager confirms that I’m using 26.5GB of VRAM while running this model. To make sure that the model can do handy stuff like search the internet, read and write files, and maintain “memory” between conversations, I use Hermes Agent (with a Docker container limiting its access to files), and LM Studio as my inference engine.
First impressions: Qwen3.8 27B makes for a thoughtful, reasonable conversation partner
Admittedly, this is a very subjective concern, but one thing that always stands out to me about an LLM is its ability to hold a conversation.

There’s no real way to measure this, but it matters. Some models just have a weird tone in their responses. Interactions can come across as forced or sycophantic, unnecessarily verbose or frustratingly clipped. Follow-up questions matter, too. Does the model extend conversations in relevant and useful ways, or does it formulaically ask an unhelpful follow-up question after every single interaction? These elements can be customized to a certain extent, but different models have a different “baseline” that colors the way they write.
And that’s the reason why I’ve never stuck with a Qwen model for very long. I’ve been impressed with their efficiency when it comes to accomplishing tasks, but I tire pretty quickly of their voice.
Qwen3.8 27B changes all that. With just a little guidance in the system prompt, the model was able to avoid some of the hangups that I’ve encountered with earlier Qwen models. Rather than the clipped, impersonal tone of earlier Qwens, it’s relaxed, even warm. Compared to Gemma 4 models, it dials back a bit of the golden retriever energy, though like most models these days it’s a bit too quick to flatter my ideas and offer to do all the things. And while it’s used the word “masterstroke” a few too many times when reacting to my ideas, I was pleasantly surprised by its willingness to offer constructive criticism and disagree with me at key points.
Frontier-level reasoning running on local hardware?
Benchmarks for Qwen3.8 27B paint a rosy picture, grading it well above average when it comes to intelligence. The numbers have it rubbing shoulders with GPT-5.6 Luna. Meta Spark 1.2 and Gemini 3.7 Flash. Claude Opus 5, Claude Fable 5, GPT-5.6 Sol, Grok 4.6, and Kimi K3 still pull ahead, but not by as much as you might think. That said, my machine isn’t even close to being able to run those models. The fact that Qwen3.8 27B offers roughly 80% of Claude Opus’ intelligence in a model that fits comfortably in 32GB is rather remarkable.
But I’m more interested in the experience of using a model than its benchmark scores. How intelligent is Qwen3.8 27B in practice? To assess the reasoning capabilities of Qwen3.8 27B, I ran it through a few workloads typical to how I use local AI.
Data analysis
First was data analysis. I fed the model six .csv files of website traffic data, about 1.6MB in total, and asked it to make sense of it all. The bad: it made some questionable assumptions based on the limited info that I provided, though a bit of conversation cleared that up. The good: it accurately figured out how to connect the column headers to the raw data, and found comparable data between the files. After 3 minutes and 45 seconds of analysis, it offered a reasonable assessment of the traffic data along with actionable, forward-thinking advice. Used on an ongoing basis, Qwen3.8 27B could be a valuable tool for keeping an eye on ever-changing data like this, though I wouldn’t let it replace my own judgment.
Image analysis
Qwen3.8 27B is quite effective at image analysis, as well. I gave it a 20MB picture from our production studio including products in the foreground and background. After 1 minute and 8 seconds of analysis time, it correctly identified the product in the foreground by name, discussed the picture’s “mood” through analysis of color, offered some commentary on some possible limitations of the picture for marketing purposes, and considered elements of audience, as well, noting that the picture would likely only appeal to a niche demographic.
Proofreading
For a final test, I put Qwen3.8 27B to work as a proofreader. Frankly, this is one of my favorite use cases for AI models. As a guy who makes his living as a writer, I really don’t need or want the AI to generate ideas for me: that’s what I bring to the table. But a detail-oriented human proofreader who has the time to painstakingly scrutinize a text across multiple revisions is hard to find. LLMs are quite good at identifying missing commas, misplaced prepositions, typos, and omissions, and if they can offer some other useful commentary along the way, so much the better.
Qwen3.8 27B effectively handled the basic proofreading duties for me, pointing out the odd errors that had slipped through my own revision process. For what it’s worth, it did miss a hyphenation error. It brought context into the mix, noting an odd moment when my brain misfired and wrote “Intel” for a CPU manufactured by AMD. The model’s general observations included commentary on potential audience reaction, and it noted a significant stylistic shift in language. It was still overly complimentary, as AI models tend to be, so I’m grateful for the human readers in my writing process. But Qwen3.8 27B makes sure that I don’t have to burden my coworkers with basic, time-consuming copy editing, which I’m sure they appreciate.
The cost of high-level reasoning
My testing run with Qwen3.8 27B demonstrated one thing quite clearly. It takes its time. This model is not shy about using lots of tokens as it reasons its way through projects and queries. Through one workday of testing and conversation, it burned through 9.5 million input tokens and 183.4K output tokens. If I were paying by the token, that one day of work would have cost me somewhere between $10 and $36 (USD).
Repeating that level of usage every workday for an entire year would add up to roughly $2,600 to $9,300 spent on just tokens. Even during the memory shortage, I can buy some badass PC hardware for that kind of outlay.

Now, one of the big draws for local AI is that it largely frees you from worrying about token usage. I’m not paying for any of this by the token. The only way that any of this hits my pocketbook is through my electricity bill. The time it takes the model to answer and perform tasks is more of a concern. Given that many tasks take minutes rather than seconds, I’d say that Qwen3.8 27B is best used for stuff running in the background. Invariably, I find myself multitasking while I let it process my latest question or instruction.
As I mentioned earlier, the model does have settings that let you adjust the time and tokens that it consumes for tasks, so don’t read this as a criticism of Qwen3.8 27B. Make some easy tweaks, and it’ll be more responsive. It gives you three settings for its reasoning capabilities: Extra High, Medium, and Low. I tend to run Extra High, simply because the advanced reasoning is the entire reason why I’m using the model, but that does mean that it goes the extra mile to think through each of its responses. If you need a snappier conversation partner, dial that back.
Qwen3.8 27B changes the game for local LLM reasoning quality
Over the last year, the conventional wisdom about local AI has looked something like this. People extolled the value of local AI for quick, efficient tasks, especially anything that can run in the background or autonomously. But for advanced reasoning capabilities, folks pointed you to frontier models running in the cloud, accessible only via paid subscriptions with per-token costs that kicked in after you hit the usage cap. That was simply the cost of business for anyone who needed a system capable of things like multimodal data analysis or non-trivial coding.

Qwen3.8 27B changes that. Using a local and private setup that I can keep fully airlocked, I can run an LLM that does everything for which I used to need cloud-based AI. I own the hardware, so I own the intelligence and I own the data. Because the model runs on my own hardware, it’s easy to maintain a local workspace for the AI. It doesn’t feel like I’m starting over every day. It picks up right where we left off.
As they say, there’s no such thing as a free lunch, and getting frontier-ish level reasoning capabilities on a home PC does come with some limitations. For Qwen3.8 27B, that’s time and tokens. More than any other model I’ve used, it responds to queries carefully and thoughtfully, going above and beyond to ground its responses in the data that I’ve provided. If I’m in a scenario where I don’t mind sending the model a task and then working on something else for a few minutes, Qwen3.8 27B works great.
The other limitation for Qwen3.8 27B is its size. It doesn’t fit into 16GB of VRAM once you factor in context and overhead, which restricts how many users will be able to access it. While there are plenty of graphics cards today that hit the 16GB mark, there’s only one current-gen consumer graphics card that ups the ante to 32GB. If an RTX 5090 isn’t your build budget, you can opt for a multi-GPU system or a mini PC with a large pool of unified system memory, but both of those approaches have their limitations, as well.

All told, if you can run Qwen3.8 27B, I can unconditionally recommend giving it a whirl. This model feels like a watershed moment for local AI. Accessing this level of intelligence without a monthly subscription is tremendously freeing, and it is unquestionably going to affect how people are going to calculate the ROI of building a PC for AI. But even if its requirements are a bit too steep for your system, there’s a lot to be excited about here. If Qwen3.8 27B shows us where local AI is headed, that’s an exciting future for anyone who prioritizes ownership and privacy in computing.