
Key takeaways:
- The “context window” of a large language model (LLM) is the amount of text, in tokens, the model can consider at once, including the instructions, the conversation so far, and the answer it’s writing.
- Context window determines working space, not intelligence. A bigger window lets the model keep more of your conversation in front of it, but it does not make a weaker model reason better.
- Bigger windows also have three real costs. They slow every reply down, because the model re-reads the entire window on each turn. They consume memory, because the model stores notes about the whole window in a buffer called the KV cache. And past a certain length, many models actually use information in the middle of the window less well.
- For most people running local AI, a window between 32k and 128k tokens is the sweet spot, with 128k and up reserved for genuinely long documents like whole books or large codebases.
If you’re running a large language model (LLM) locally, you’ve almost certainly seen a number in your settings called the context window. Maybe you assumed that bigger was better, as with display refresh rates or storage drives. The truth is more subtle. Bigger can be better, but it can also be counterproductive.
The context window is one of the most misunderstood settings in local AI. Setting it incorrectly can cost you speed, memory, and in some cases, the quality of the answer you get back. But one size doesn’t fit all. Some use cases actually benefit from a very lean context window, while others require all they can get. But for most folks running an agent PC, the best approach is actually to take the middle road with a context window that’s sized according to their workflow.
In this guide, we’ll help you with this crucial part of working with LLMs. We’ll explain what a context window actually is, why “bigger” isn’t automatically “better,” how it really relates to a model’s reasoning, how to right-size it for what you actually do, and which of the other settings in your server matter just as much. By the end, you’ll be able to look at your context window setting and know whether it’s helping you or quietly working against you.
What is a context window, really?
The cleanest way to picture a context window is to think of it like a desk. A large language model doesn’t carry a persistent memory of your conversation the way you do. On every single turn, it looks at everything that’s on the desk: the system instructions, the full history of the chat, and whatever new message you just typed.
The context window houses all that data. In the same way that desk space is measured in square inches, a context window is measured in tokens, which are roughly chunks of a word. A token is a little shorter than a word on average, so a good working guess is about four characters per token, or one token per three-quarters of a word. That means a 100k-token window holds roughly 75,000 words of text, which is about the length of a full novel. (Keep in mind that the ratio is an English one. For Japanese, Korean, or code, a token covers far fewer characters, so the same window holds noticeably less text.)
Every model has a maximum context length it was trained to handle, and that’s a ceiling baked in by its designers. Your server can then be set to use anywhere from a small slice of that ceiling up to the full amount. When you see a “context length” setting in LM Studio or a similar tool, you’re choosing how much of the model’s trained ceiling you actually want to put on the desk. Setting it below the ceiling is not only possible, but often the smarter play. (Some backend engines allow you to do the opposite and manually override the ceiling, but that’s more of a workaround for power users than a recommended best practice.)
One more distinction worth making: the context window is the total, but part of it is reserved for the model’s own output. Every model sets aside a slice of the window for the answer it’s about to write, so the most it can read (its input length) is smaller than the total window. If your setup lets you set input and output lengths separately, that’s this same trade-off in disguise, and the input figure is the one that actually has to fit your conversation and documents.
What is the benefit of increasing the size of the context window?
Increasing the context window for an LLM can be incredibly valuable. It allows the model to hold more tokens in active memory, enabling it to apply its reasoning capabilities to more data at once. Let’s say that you’re a small business owner using local, secure AI to scan for anomalies between your inventory and financial reports. The best way for the model to handle that task is to hold both full reports in its context window without summarizing.
Equip an LLM with a small context window, and it acts a bit like a goldfish trying to order off a very large restaurant menu. By the time it gets to page two of the menu, it’s already forgotten what’s on page one. When it comes time to order, it knows it has to say something, so it points at something on the last page that it read.
As you’re working with LLMs, you might well run across a moment that calls for a larger context window. If you need your model to turn a pile of scattered notes into a fleshed-out timeline for your novel, it’ll need a big context window. Perhaps you’re tasking your model with a project that has a long list of requirements. Your model will need a context window that’s large enough to hold those requirements in view alongside the data specific to the project.
What context window do popular models have?
These vary widely, and it’s worth knowing the ballpark before you go in. Not that long ago, it was fairly common to see LLMs with a 32K max context window. Today’s models are typically capable of reaching quite high figures, with multiple recent options like Qwen3.8 27B maxing out at 256K tokens natively.
A couple things to take away from this. The maximum size of the window is a property of the model, not the server, so you can’t force a native 128K window onto a model that was only built for 32K. The number keeps climbing, with newer models in each family pushing the ceiling higher over time.
Second, it’s quite common for today’s models to offer a larger context window than many PCs can handle without overflowing VRAM. We’ll walk through some of the math shortly, but many modern models won’t have any trouble saturating the available VRAM of an 8GB or even 16GB graphics card. KV-cache quantization can reduce the footprint of the memory buffer, potentially allowing you to fit a larger window within your card’s memory, albeit with some loss of precision.
Why doesn’t a bigger window mean a smarter model?
This question gets right to the heart of the most common misunderstanding with context windows. The context window and the model’s reasoning ability are two separate things. Mixing them up is why people buy into the “bigger is better” idea in the first place.
The context window is the workspace. It determines how much of the conversation and documents the model can see at the same time. Nothing about the window changes how the model thinks. Whether it reasons carefully or carelessly is a property of the model itself, of its training, its size, and its architecture. Two models that are identical in every way except window size will demonstrate the same reasoning abilities whether they’re given a bigger or smaller desk. A 27-billion-parameter model with a 128k window doesn’t reason better than the same model with a 32k window. It just has room to look at more at once.

This matters, because it reframes the whole decision. You might well have reasons to pursue a larger context window, but intelligence isn’t one of them. Pick the model based on the capabilities of your PC and level of reasoning that you require, and then separately set the context window based on the amount of material that you actually need the model to “keep in mind” as it works.
Those are two independent dials. One of the most common local-AI mistakes is turning the second one all the way up and expecting the first one to improve.
What does a bigger window actually cost you?
At this point, you might be wondering why it would be a problem to increase the context window. Why can’t your local AI model simply keep more data in view as it works? Running a larger context window incurs three costs, and all three can create problems for your local AI setup.
The first is speed, and it’s the one you’ll feel first. Because the model re-reads the entire context window on every turn, a long conversation gets slower with every message you add. During text generation, the model re-consults the KV cache to produce every single token, and that repeated reading pulls a large amount of data across the memory bus on each step. The constant data movement saturates memory bandwidth, and that can create noticeable lag. (Side note: that’s why memory bandwidth, not just memory capacity, is so important for local AI.) The very first reply in a fresh chat is fast, because there’s little on the desk. By the fiftieth message, the model has to re-read a mountain of earlier text before it can answer the thing you just asked.
The second cost is memory, and this one can actually stop your model from loading. To answer a question about a long conversation, the model keeps a running set of notes about everything it has processed, and those notes live in a buffer called the KV cache. The KV cache grows in direct proportion to the window length. Double the window and you roughly double that memory draw. On a consumer graphics card with 16GB or 32GB of VRAM, a very large context window can eat a big chunk of your memory, and that’s before you even count the model’s own weights. A window that fits the model’s ceiling on paper can still overflow your card in practice, forcing the entire operation to run at a snail’s pace or even bringing it to a grinding halt.
The third cost is quality, and it’s the one most people never expect. Research on long contexts keeps finding the same pattern: models use the beginning and the end of a long window well, but they use the middle less reliably. This is sometimes called the “lost in the middle” effect. Going back to the metaphor of a desk: if your desk is only big enough to hold two or three papers, you’ll probably benefit from getting more workspace. But spreading all your papers across a desk the size of a gymnasium won’t help, as it’ll probably make it harder to find all the information you need. In plain terms, if you paste a 60,000-word document into a 128k window and ask a question about a detail buried on page 30, the model can do worse at finding it than it would on a shorter, tighter window where that detail sits closer to the edges. A bigger window doesn’t just cost you speed and memory. Past a point, it can quietly cost you accuracy.
To sum up: perhaps you’re asking the question “is a bigger context window better?” The answer might be yes, but only to a point. A larger context window is better at one thing, and worse at three. It’s better at holding more material in front of the model. It’s worse at speed, memory, and, beyond a point, at using what’s in the middle. The trick is to figure out how to get a large-enough context window for your workflow while minimizing the impact of the trade-offs.
How do you pick the right context window size?
You pick it from your actual workload, not from the number in the spec sheet. Here’s what the decision-making process looks like in practice.
The first step for determining your context window size is to figure out what will fit in your graphics card’s VRAM. Your model’s weights will take up a chunk of that space. It’s best to leave some margin open to avoid system hangups or slowdowns. The remaining space is what you have available for your context window.
But don’t assume that you need to use all that space. Often, it’s best to only claim a percentage of it. For everyday chat, drafting, and short tasks, you rarely need much more than 8k to 32k tokens. That’s plenty for normal conversations, email, summaries, and most day-to-day writing. If you’re running a model locally for this kind of work, a modest window keeps you fast and leaves your memory free for the model itself.
For agentic work, coding across a project, or working with long documents, 32k to 128k is the sweet spot. The autonomous AI agent framework Hermes, for example, requires a model with at least a 64K context window. A context window around this size is where most local AI users should live. It’s large enough to hold a full project, a long conversation, or a sizable document, while still leaving headroom for speed and memory. If you’ve been chasing a 256k or 512k window and it’s been slow, this is the setting to bring back down.
For genuinely huge inputs, whole books, large repositories, or long multi-document analysis, 128k and above is where you go, and you accept the cost. To be clear, context windows this large serve specialist use cases. If you’re not regularly feeding the model something that large, the window is just sitting there taxing your speed and memory for no benefit.
| Context window | Rough size | Memory cost | Best for |
|---|---|---|---|
| 8K | ~6,000 words | Minimal (Under 2GB VRAM) | Everyday chat Drafting Short tasks |
| 64K | ~48,000 words | Medium (5GB – 10GB VRAM) | Most local-AI work Long conversations |
| 128K | ~96,000 words | High (10GB – 20GB VRAM) | Larger datasets Complex projects Agentic orchestration |
| 256K+ | ~190,000 words | Very high (20GB+ VRAM) | Large codebases Multi-document work |
The memory column lays out the blueprint for your setup. Loading a model’s weights claims a large, fixed chunk of your VRAM up front. Expanding your context window adds a dynamic KV cache footprint on top of those weights. At 128k tokens, for a mid-size model in full precision, that buffer alone can swallow 10 to 20 gigabytes of memory. A context window setting that looks reasonable in isolation can easily push your combined memory demand past your card’s physical capacity, causing system hangups or severe performance drops.
Can you fit a large context window into a small memory footprint?
Perhaps you need a larger context window for the task at hand, but you’ve already saturated your available VRAM. Several hardware and software levers can help fit that data into a smaller footprint.
First, your choice of model architecture makes a big difference, as that sets the baseline efficiency. Modern models with Grouped Query Attention (GQA), such as Llama 3, drastically reduce the memory footprint of the context window right out of the box, no extra effort required. Choosing a GQA-enabled model can give you the benefit of a larger context window while using much less VRAM than an older model architecture would require.
Second, your server software should give you options that can compact your active context. LM Studio gives the K cache and the V cache each their own quantization setting. Enabling both at 8-bit compresses the running memory buffer and can roughly halve its footprint; 4-bit shrinks it further. While software often flags these options as “experimental” due to (usually slight) precision tradeoffs, most users find the massive VRAM savings worth the minor quality impact.
Finally, you might find it worthwhile to offload the context window to system memory. When your context window exceeds your graphics card’s physical capacity, modern local servers can offload the surplus KV cache directly into system RAM. While system RAM operates slower than VRAM, fast DDR5 memory and high-bandwidth PCIe slots on a modern motherboard can keep performance moving forward, allowing you to process massive documents without crashing your session.
How do you pick the size of a context window for an agentic framework like OpenClaw or Hermes?
Thus far, we’ve been thinking about context window size from the perspective of a direct inference engine like LM Studio or Ollama. These platforms are an easy way to get started with local AI, as they give you a single app for downloading, running, and interacting with models. This architecture excels at real-time interactive chat, focused single-document analysis, low-overhead drafting, and rapid local prototyping.
In 2026, agentic AI has become one of the most talked-about directions in local AI, alongside the direct-inference engines that most builders already rely on. Agentic frameworks add a layer on top: instead of prompting the model step by step, you hand it a priority and it runs multi-step, autonomous workflows across it. For multi-day projects, that’s a different class of machine, and it has different context-window needs.
Setting context windows for agentic frameworks requires a balanced approach. Selecting a context window large enough to cover an agents’ daily workload appears challenging at first. But most agents actually run quite well with relatively modest context windows. Most such frameworks operate at peak efficiency within a 32k to 64k token window. Some, like Hermes, ask for a context window at the upper end of that range, and the tools that you use might call for a bit more. This specific range provides ample workspace for multi-step scratchpad reasoning, tool execution logs, and detailed system instructions, while preserving enough GPU memory bandwidth to guarantee fast generation speeds.
How do agentic architectures maintain fast response times over continuous runs, even as data accumulates in the context window? Agentic systems have another lever, and it’s one that changes the whole picture: summarization. It solves the long-conversation problem without requiring a bigger window. Agentic frameworks automatically compress older parts of the conversation into a short summary once it grows long. The model keeps the gist of everything you discussed, drops the raw back-and-forth, and frees up the desk.
Retrieval-augmented generation (RAG) further expands total data capacity across both direct inference platforms and agentic frameworks. In direct local inference apps, RAG operates as a targeted document search engine. The software stores files, retrieves relevant text snippets matching your prompt, and passes only those specific chunks to the model. Agentic frameworks integrate RAG as an active, long-term memory bank. The agent dynamically queries its external database, pulling targeted historical data into focus only when a specific sub-task demands it. This dual-layer memory strategy keeps active context windows lean, protects memory bandwidth, and empowers your agent PC to drive large-scale projects across massive file libraries.
All that means that you don’t need to push the context window length of your agentic AI system to the absolute maximum. Your agent PC can keep focus on large projects and sustain long conversations, all without paying the cost of a huge window.
Can you run a model even if the context window overflows VRAM?
This is a very common question. Often, it’s asked by people trying to see how much value they can get out of their current PC hardware. Other times, it comes from local AI enthusiasts looking to check out a new, relatively large model, even if they don’t have sufficient VRAM for the weights, context window, and overhead. It’s important to note here that local AI engines do have tools for easing this situation, and while those solutions have drawbacks, they’re worth considering.
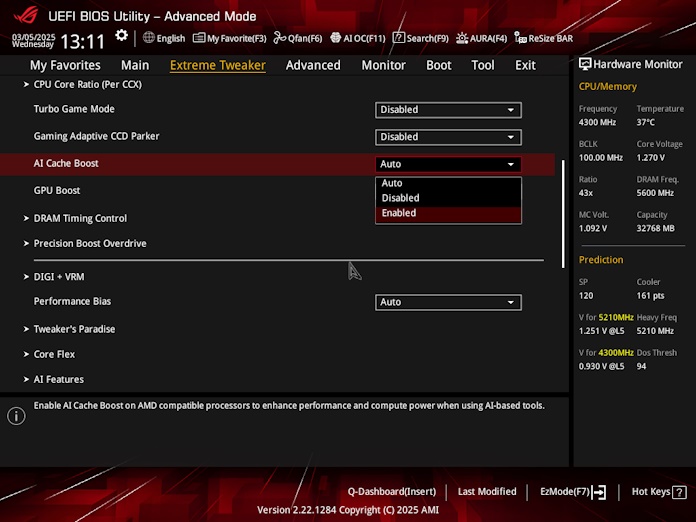
To navigate this question, it’s important to understand what happens when VRAM overflows. Your local AI engine can offload the excess KV cache to system RAM. The trouble with this is that the pathway between your system RAM and the GPU cores is much longer than the pathway between VRAM and the GPU cores, slowing down your experience with your agent PC. Just how much slower depends on lots of variables, including your motherboard, memory, and BIOS settings. You can mitigate the performance loss by using a motherboard with PCIe 5.0 bandwidth for the expansion slot, running high-speed DDR5 memory, and offering BIOS features like ASUS AI Cache Boost, which can optimize the full computational pathway from your GPU through CPU, cache, and memory. Available on ASUS 800 and 600 series motherboards paired with an AMD Ryzen 9000 series CPU, AI Cache Boost targets exactly the performance hit that comes from oversaturating your graphics card’s VRAM. In our own testing it lifted local chatbot performance by about 15% on its own, and up to nearly 30% when combined with faster system memory.
When your PC has to manage VRAM overflow, its responses won’t be nearly as snappy. But depending on how you’re using your agent PC, that might not be a big concern. As long as your system can handle VRAM overflow without grinding to a halt, you can let an advanced model capable of high-level reasoning work its way through a complex project while you focus your time and effort somewhere else.
What settings should I adjust for fast, responsive local AI?
As we’ve seen, context window length matters, but scaling it endlessly eventually creates performance bottlenecks. So what do you do if your AI setup stalls out when conversations run long or when you give it a data-intensive task? If increasing the context window isn’t the answer, what is?
First, a simple and practical suggestion that requires no fiddling with settings whatsoever. Sometimes you just need a new chat session. A stale server session is a classic cause of sudden, unexplained lag. Running a server continuously can degrade performance over time. Restarting your local backend clears the accumulated cache and immediately restores baseline text generation speeds. If your model was fast an hour ago and is now crawling with nothing changed, the easy first move is to restart the server, not to dig through your settings.
Second, you might try out agentic AI. Frameworks like OpenClaw and Hermes are more approachable than their power-user reputation suggests, and they have built-in tools for dealing with the long-term pileup of context and data. These platforms continuously summarize conversation histories and execute targeted RAG retrieval in the background, keeping your active token count low and your generation speeds high.
Third, you might benefit from exploring the latest model options. If you found a favorite early in 2026, or even back in 2025, and haven’t tried out some of the models that have been hitting the scene in recent months, you potentially have a lot to gain from looking at the latest and greatest. The AI ecosystem is moving fast on all fronts.

Finally, it’s worth taking a look at your hardware setup, as well. At the end of the day, the capabilities of your PC act as a hard limit for what you can accomplish with local AI. A graphics card with more VRAM and a wider memory bus could provide the raw memory bandwidth needed to shuttle large KV caches into compute cores without latency. A motherboard with PCIe 5.0 bandwidth and DDR5 support can maximize data transfer speeds when your system offloads excess memory buffers from GPU VRAM into system RAM. And a fast NVMe SSD can accelerate model loading times and speed up vector database retrieval during local RAG operations.
Unlike the other solutions for fast local AI that we’ve listed here, new PC hardware isn’t free. It’s an investment, and maybe more than you’d like given the current memory shortage. But if you’ve identified a valuable use case for local AI and you’ve already optimized your current agent PC about as far as it will go, it’s time to consider a solution that will give you the level of performance that you need. The hardware is out there, and the return on your investment could be quite large.

Frequently asked questions
Is a bigger context window always better?
No. A bigger window lets the model hold more of your conversation and documents in front of it at once, but it costs you on three fronts: speed, because the model re-reads the whole window every turn; memory, because the KV cache grows with window length; and, past a certain size, quality, because many models use the middle of a long window less reliably. The right size is the one that fits your actual workload, not the largest one you can load.
Does a bigger context window make a model reason better?
No. The context window is working space, not intelligence. It determines how much the model can see at once, not how well it thinks. A model’s reasoning ability comes from its training, size, and architecture, not from its window. You pick the model for the reasoning you want, keeping in mind the capabilities of your agent PC, and then separately pick the window for the amount of material you need to hold.
How much context window do I need for local AI?
For most people, 32k to 128k tokens is the sweet spot. Everyday chat and drafting rarely need more than 8k to 32k. Long conversations, coding across a project, and sizable documents live comfortably in the 32k to 128k range. 128k and above is for genuinely large inputs like whole books or large codebases, and comes with a real speed and memory cost.
Why does my local model get slower as a conversation goes on?
Because the model re-reads the entire context window on every turn, so each new message adds to what it has to process. The longer the conversation, the more it re-reads, and the slower each reply becomes. This is expected behavior, not a hardware problem. Prompt caching, when available, and automatic summarization of older turns are the two main ways to keep a long conversation fast.
What’s the KV cache, and why does it matter?
The KV cache is the buffer where the model keeps its running notes about everything it has processed, and it grows in direct proportion to the context window length. It’s one of the biggest consumers of graphics-card memory in a local setup, which is why a long window can overflow a 32-gigabyte card even when the model’s weights fit. KV cache quantization compresses this buffer so the same window uses less memory.
Should I set my context window to the model’s maximum?
Usually not. A model’s maximum context is a ceiling, not a target. Setting the window to the ceiling might be necessary for the work you’re doing, but too often it incurs steep costs to speed and memory for tasks that just don’t benefit from the larger window. Set it to the size your actual workload demands, and only go to the maximum when you’re regularly feeding the model material that large.